
 PocketArC
The cost of intelligence is dropping unbelievably fast.
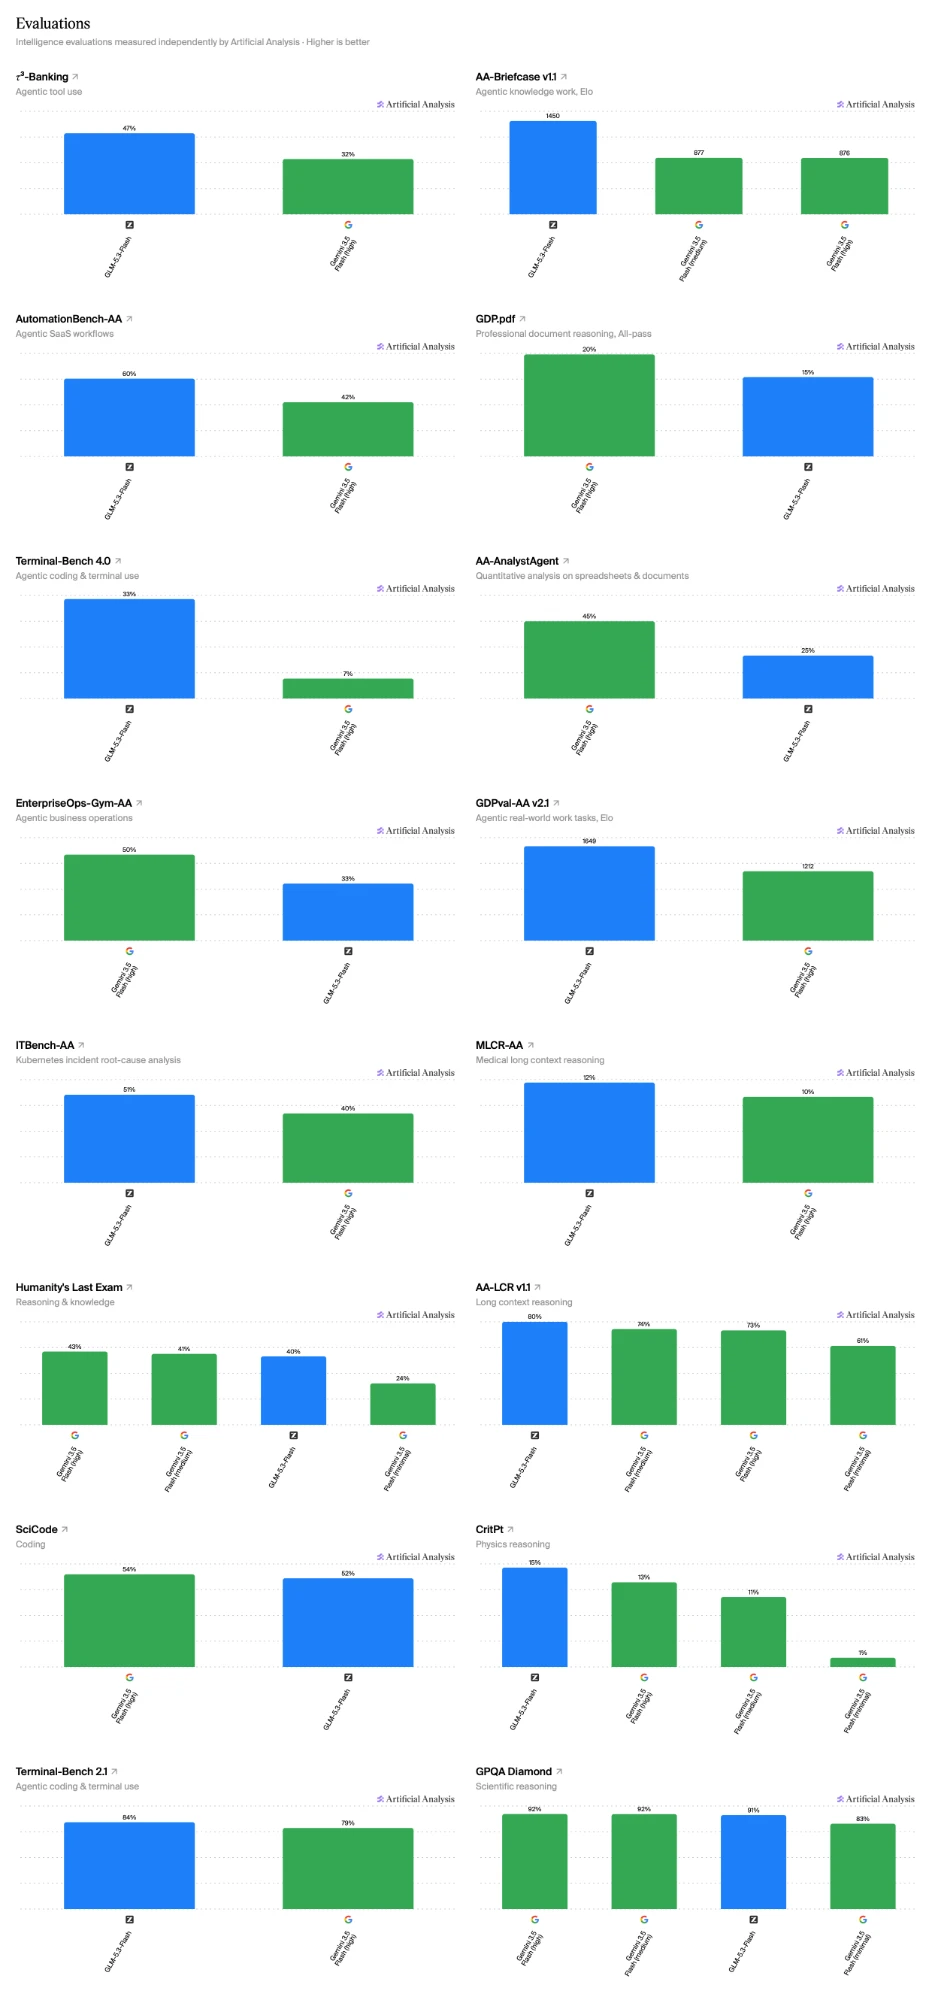
In July, I built a tool to read listings from a marketplace, screenshots and all, and analyze it to extract listings that mattered to me, based on their descriptions, with Gemini 3.5 Flash. It now runs on Z.ai’s GLM 5.3 Flash, and it performs better in benchmarks (snapshot) and my own evals.
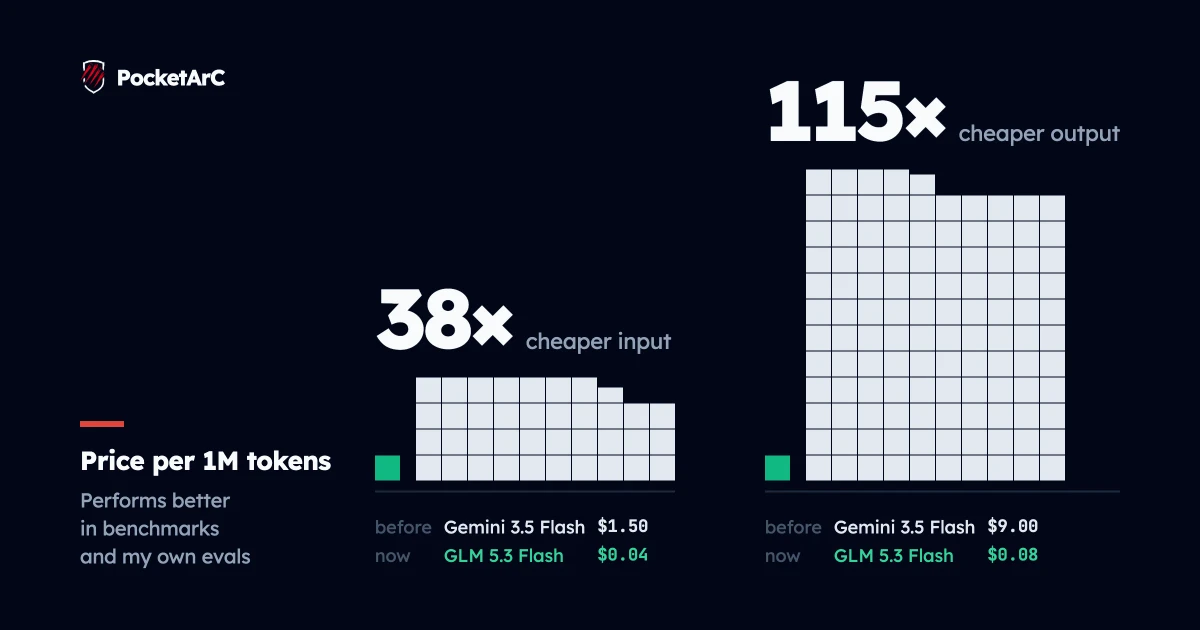
OpenRouter prices per 1M tokens, in USD1:
| Model | Input | Output |
|---|---|---|
| Then: Gemini 3.5 Flash | $1.50 | $9.00 |
| Now: GLM 5.3 Flash | $0.0399 | $0.0784 |
That’s ~38x cheaper for input and ~115x cheaper for output.
In my tool’s database, going through 1000+ listings cost me $17.75 with Gemini, which at the time I thought “eh it’s only $20, it’s worth it”. At today’s rate, those same listings would have cost about $0.54. Insane cost reduction.
While I’m writing about this: I’ve also seen people argue that GPT-6 Luna is too dumb to be the default chat model when you’re paying API rates instead of subsidized subscription costs. Out of curiosity, I compared GPT-6 Luna (max) with Claude Opus 4.8 (max) on Artificial Analysis (snapshot), and Luna is basically the same or better on most of the evaluations.
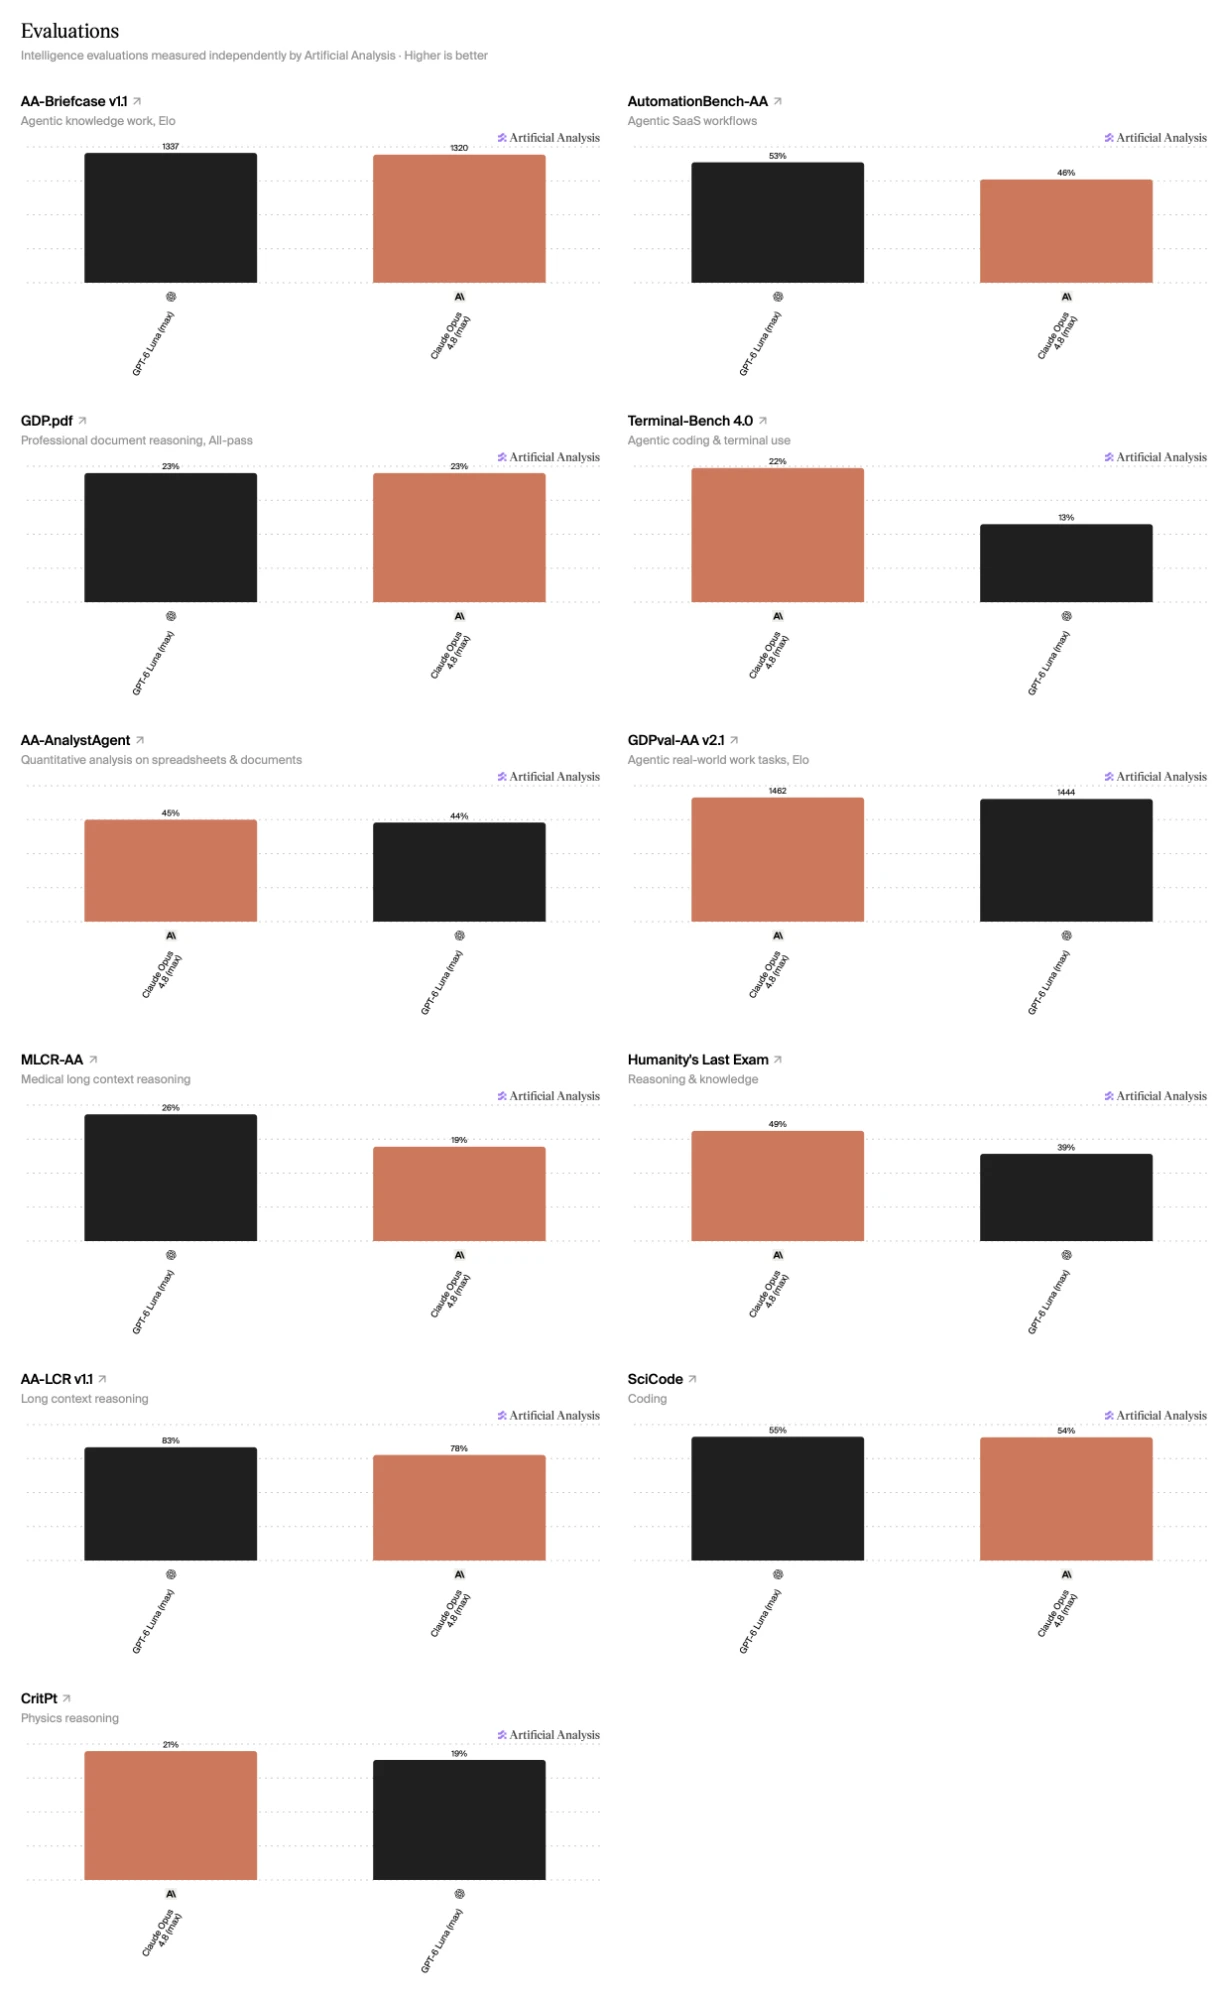
Opus 4.8 was Anthropic’s flagship Opus until Opus 5 came out on July 24, less than four months ago. On the API, Luna costs $0.10 per 1M input tokens and $0.50 per 1M output tokens. Opus 4.8 costs $5 and $25. In, what, 4 months? The cost of that level of intelligence dropped 50x, and now people argue that you shouldn’t use Luna because it’s too dumb.
Unreal progress. Even more unreal is how our expectations just keep increasing month by month. Fable 5.2 just came out - are we going to see Fable 5.2 intelligence in the next 6 months for another 50x price drop? I guess we’ll find out.
Footnotes
-
I always use OpenRouter for tiny LLM work. If I was spending thousands I’d wanna go direct to the providers, but for my small projects OpenRouter is just so easy to swap models and experiment with everything. ↩